Topic of the day: Data Preparation - a crucial first step for every AI project.
As much as 70% of the work in AI projects revolves around preparing data. In this phase, you make sure the data is correct, relevant and realistic. Here are a few insights I would like to share:
🔹 Data with a purpose: We start with the question: "Is our goal achievable?". Perfection does not exist and AI cannot solve everything, but with the right data it can provide valuable insights and good support, making our work easier and more efficient.
🔹 Variation is key: Whether it concerns historical data, photos, text or sound, a dataset should contain as many different situations and contexts as possible. This makes a trained AI model more robust and accurate.
🔹 Quality over quantity: A well-balanced dataset is more important than an enormous amount of data. Sometimes less data, but with more variation, can produce better results than simply more of the same.
🔹 Creative solutions: When developing real-world use cases, you sometimes need to think outside the box. Example: in a packing process, the correctness of packed items had to be checked, but items in plastic packaging were difficult to distinguish in photos. Adding coloured stickers helped make the different types of items in plastic packaging easier to recognise. Sometimes AI just needs that little bit of extra help...
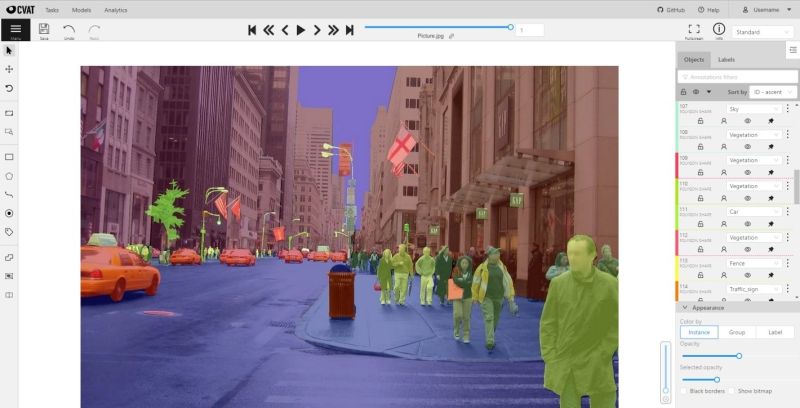
🔹 Labelling: Clear and accurate labelling is essential for AI models. It can sometimes be a "painful" process, but smart tools and techniques, or professional labelling services, are making it increasingly easier and more efficient. A good dataset increases the chances of a good AI model.
Thanks to HOWEST University of Applied Sciences for this inspiring kick-off - on to the next session! 🚀